DeepSeq.AI Takes the Hyperscaled Protein Training Data to the SynBioBeta 2026 Main Stage
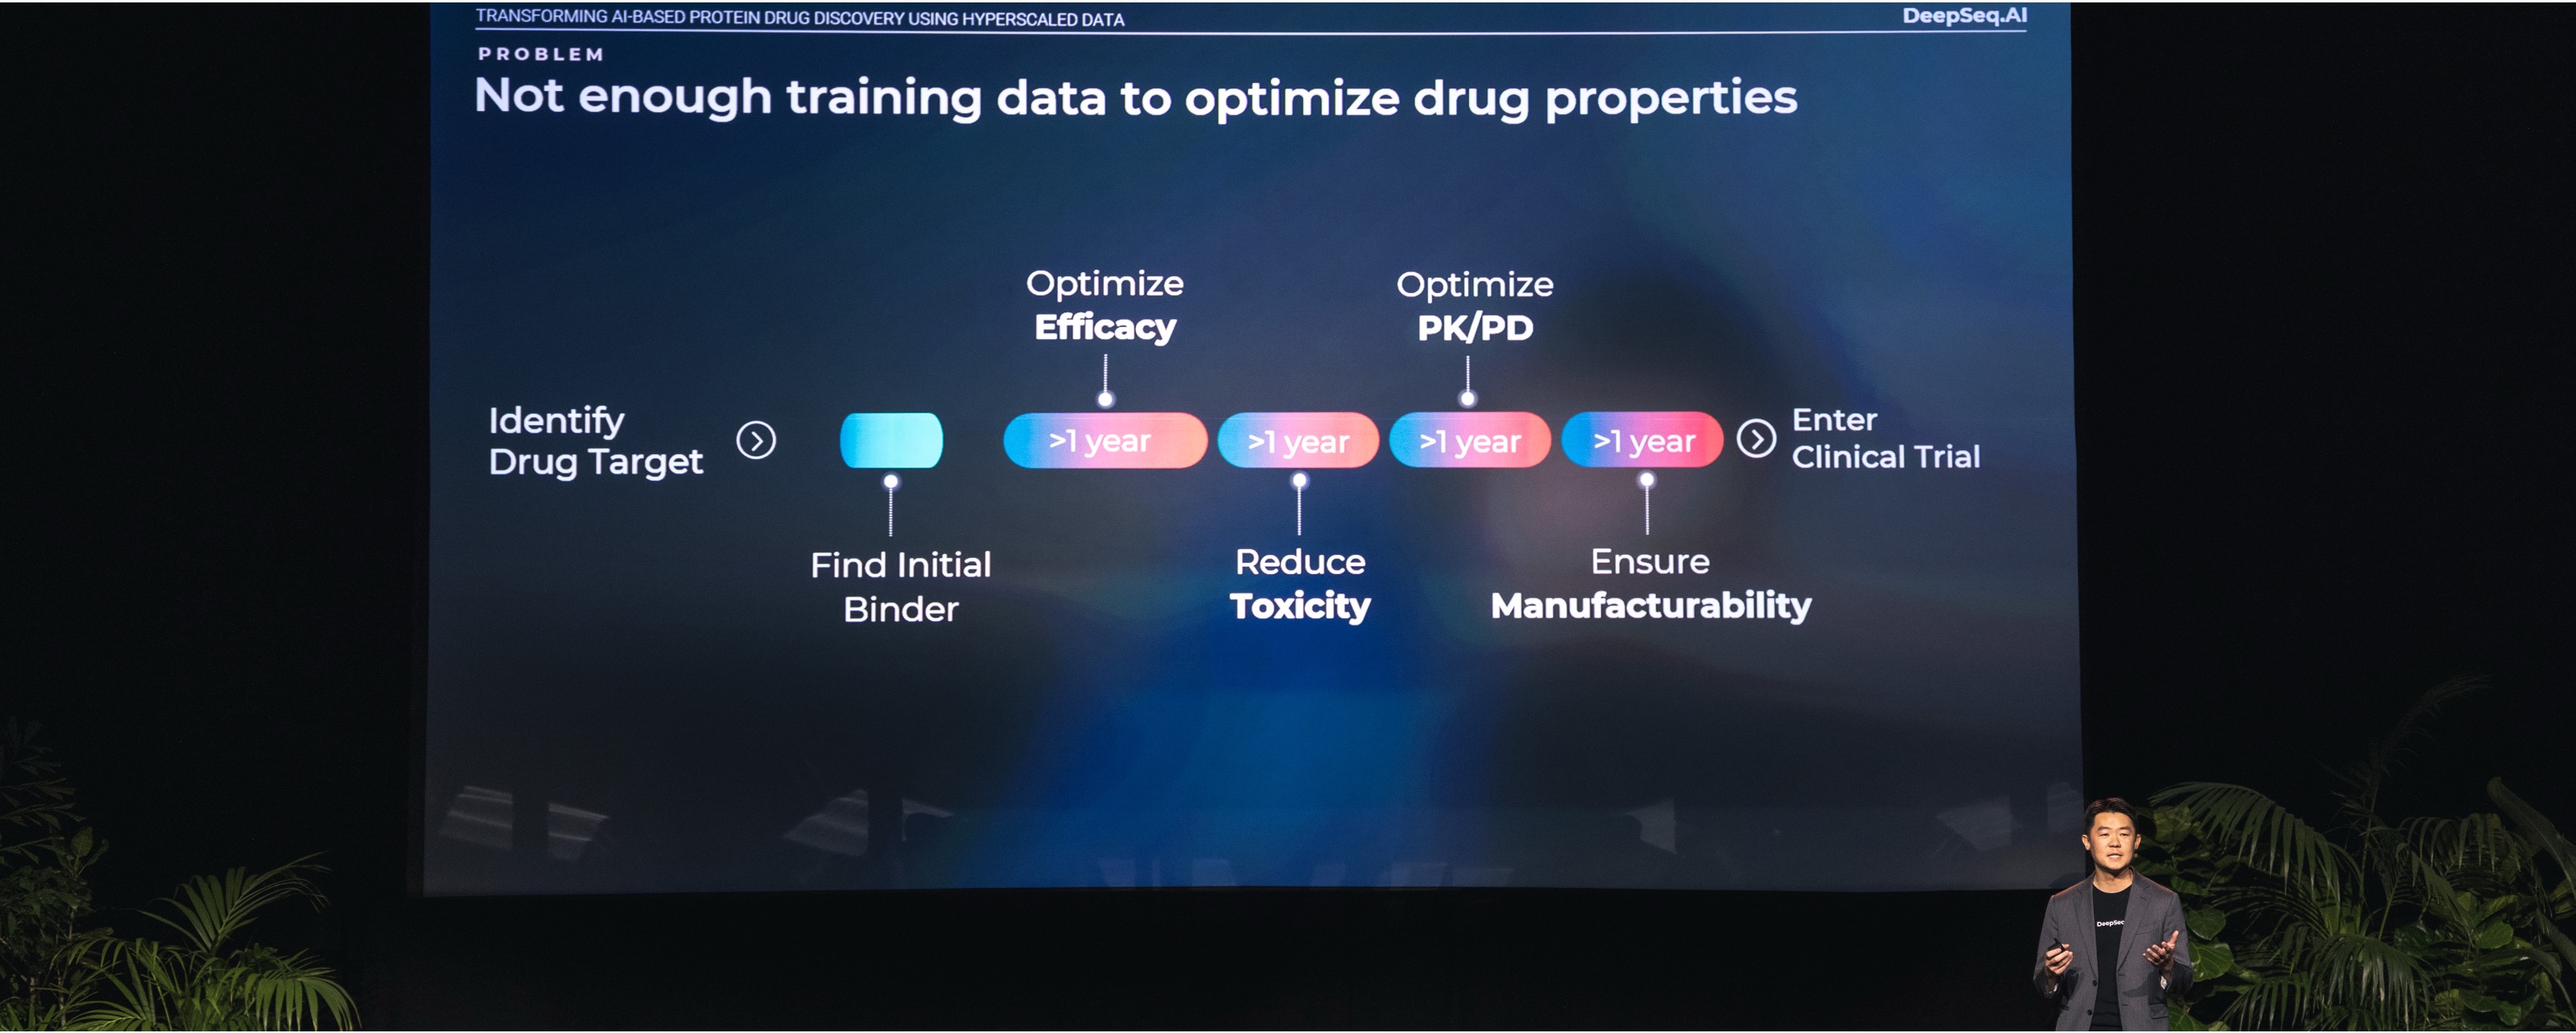
Developing a binder today seems like a solved problem. Developing a drug is not.
That was the argument Andrew Chang, DeepSeq.AI's CEO and Co-founder, made on the SynBioBeta 2026 main stage on May 5, in a spotlight talk titled “Decoding the Grammar of Protein-Protein Interactions: A Function-First Paradigm Shift.”
The field has become very good at generating binders. Efficacy, affinity maturation, toxicity, PK and manufacturability are still unsolved, and Andrew argued they are challenging for a specific reason. The training data went into most structure models is static, however, biology is not.
DeepSeq takes a Function-First approach instead: an end-to-end platform spanning library design, cloning, cell engineering, screening, sequencing, model training and inference, which explores protein-protein interactions at a scale no structure dataset reaches. In one validated project, DeepSeq quantified over 10 billion antibody-antigen interactions and their affinities in a single experiment.
The talk closed on immunogenicity. Two commercial nanobody drugs with very different clinical safety profiles look different in how each one engages the human immune receptor space. Seeing that signal before the clinic is what changes drug development economics.
Thank you to John Cumbers and the SynBioBeta team, and to everyone who came to find us afterward.
News & Updates
The latest research milestones, partnerships, and company updates.